Dedicated tokens
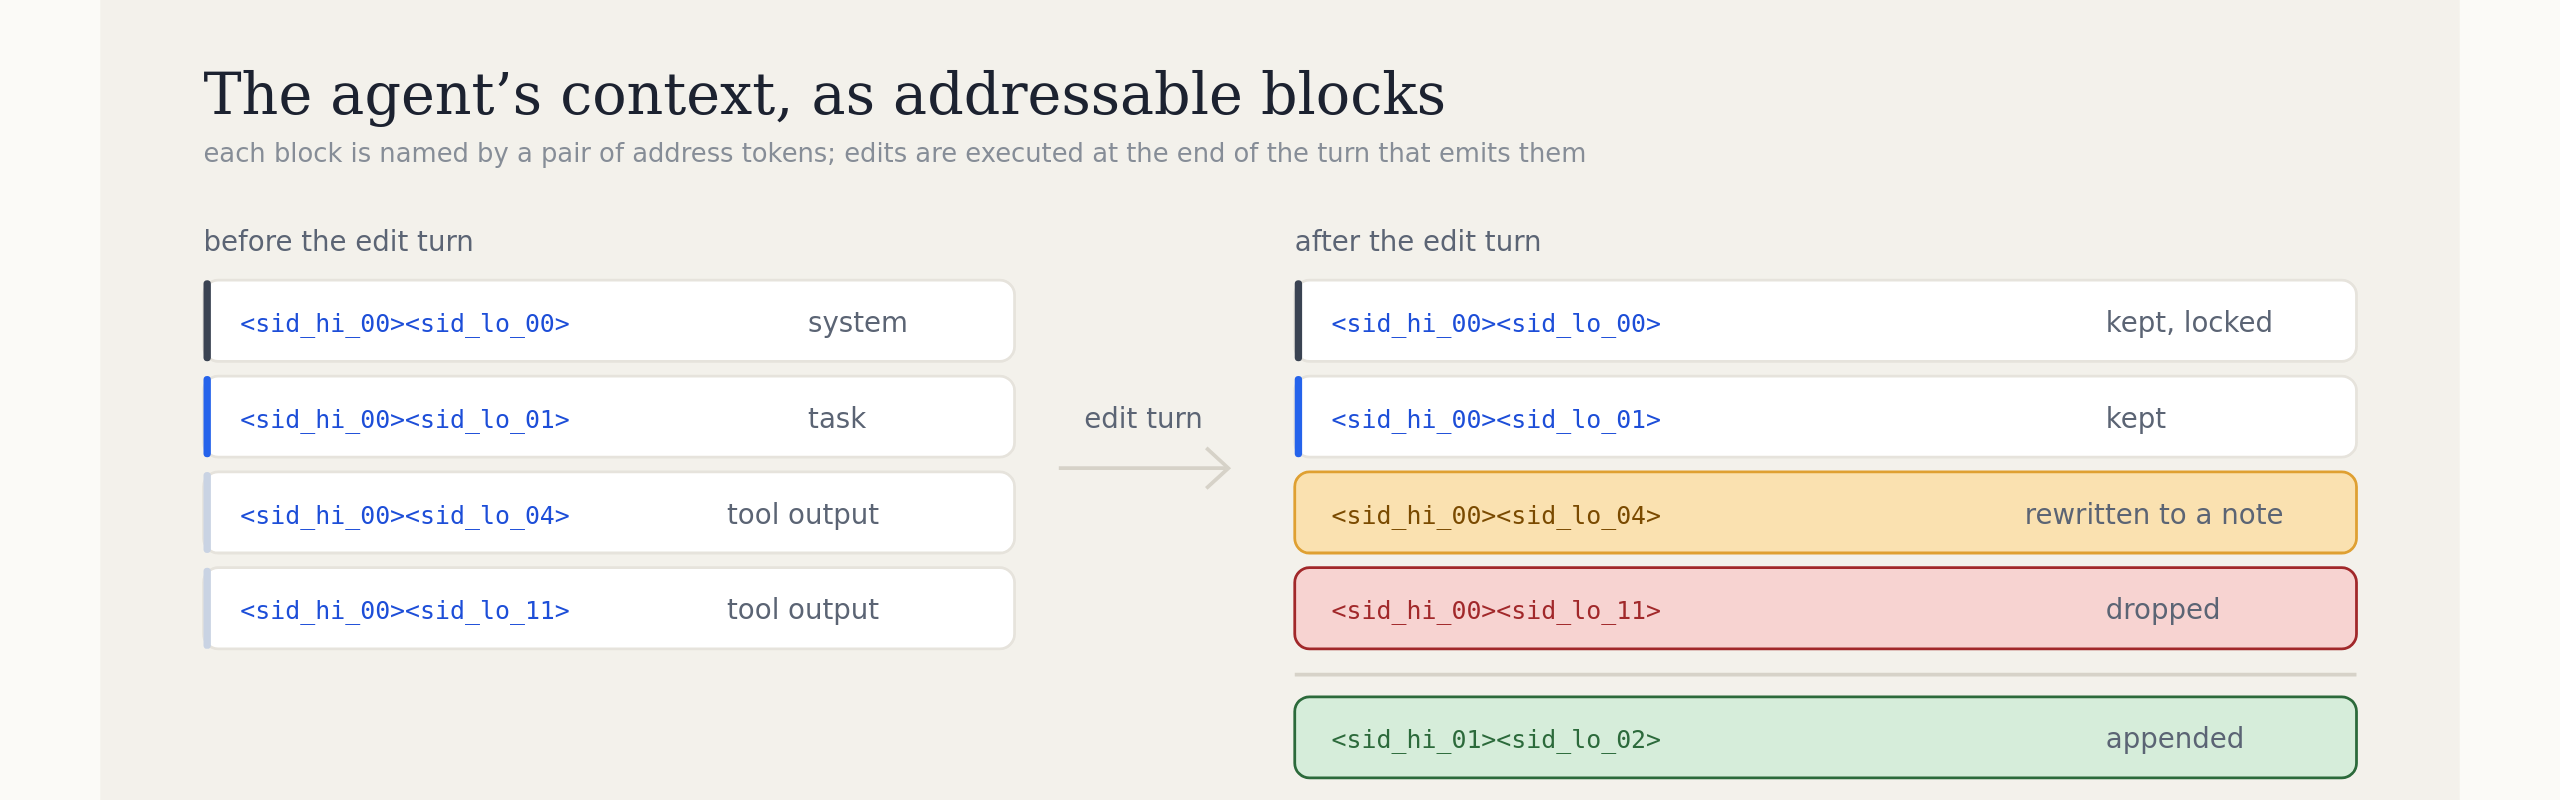
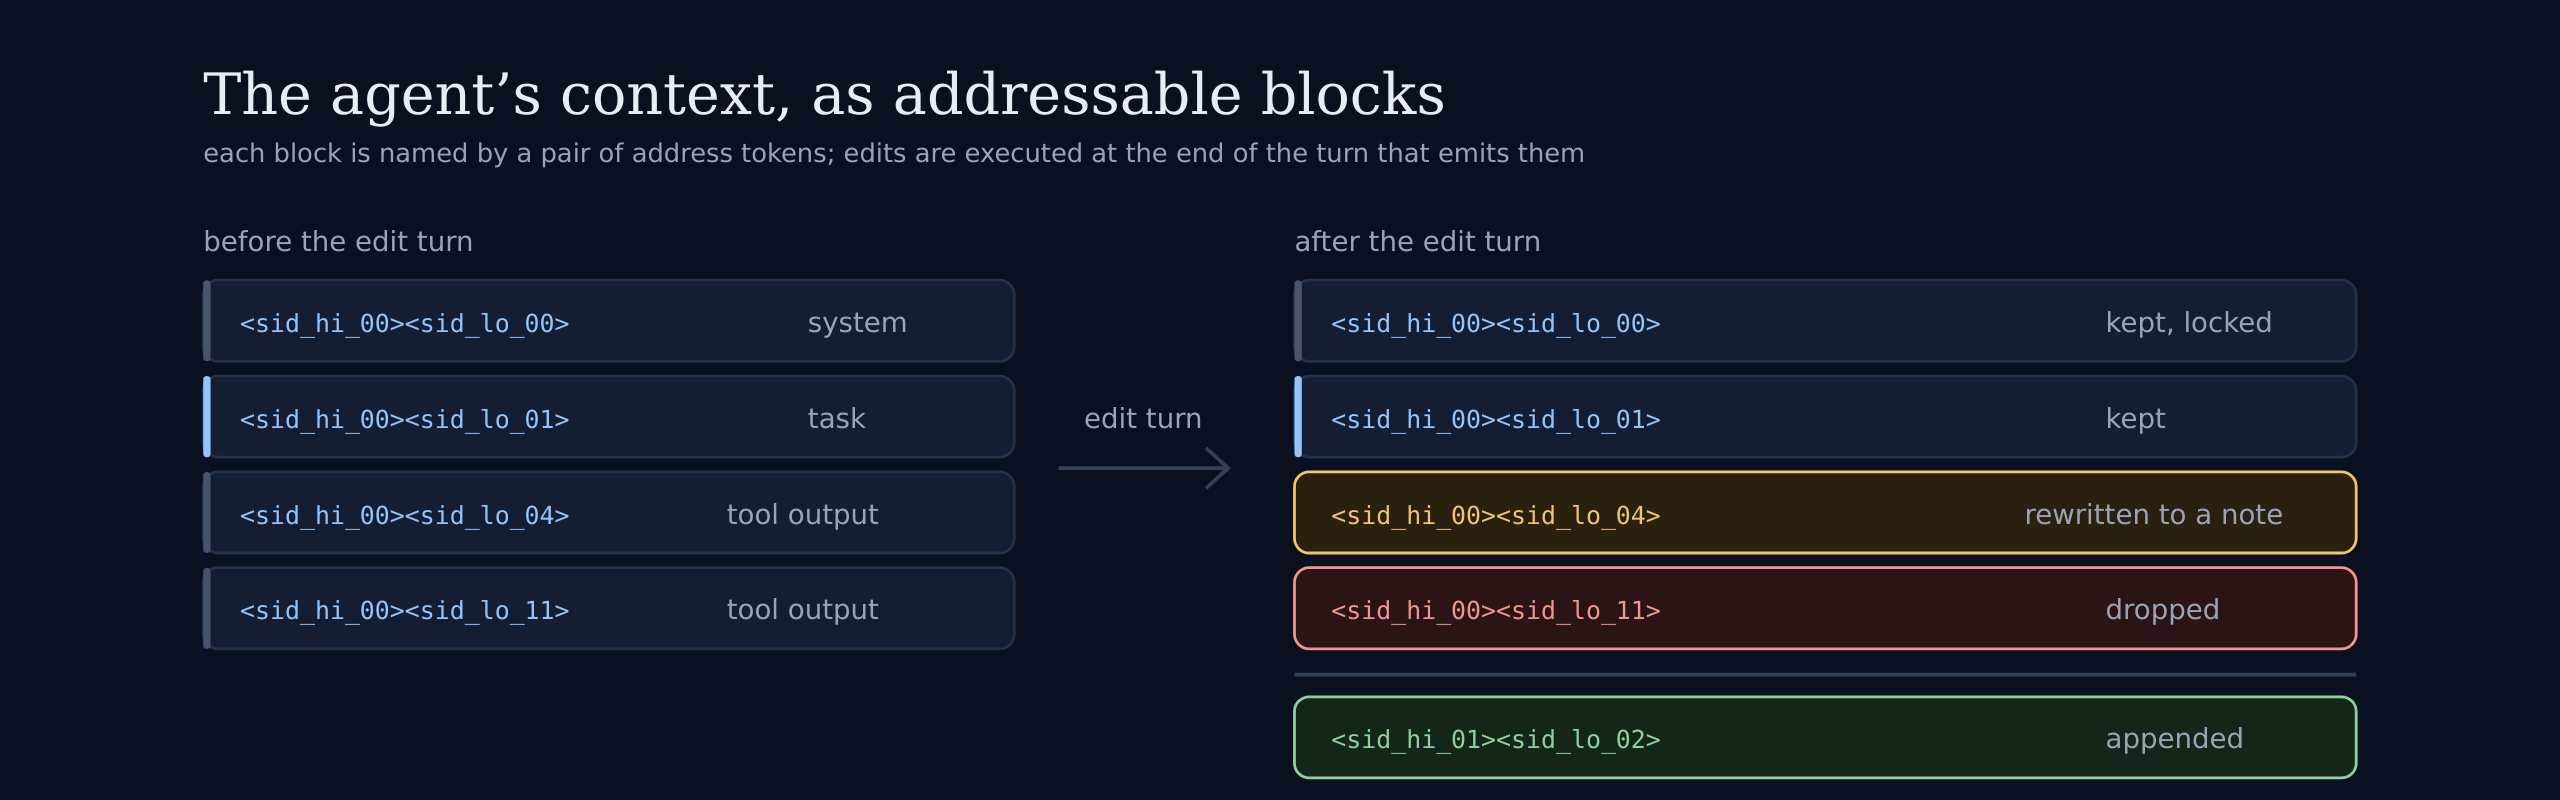
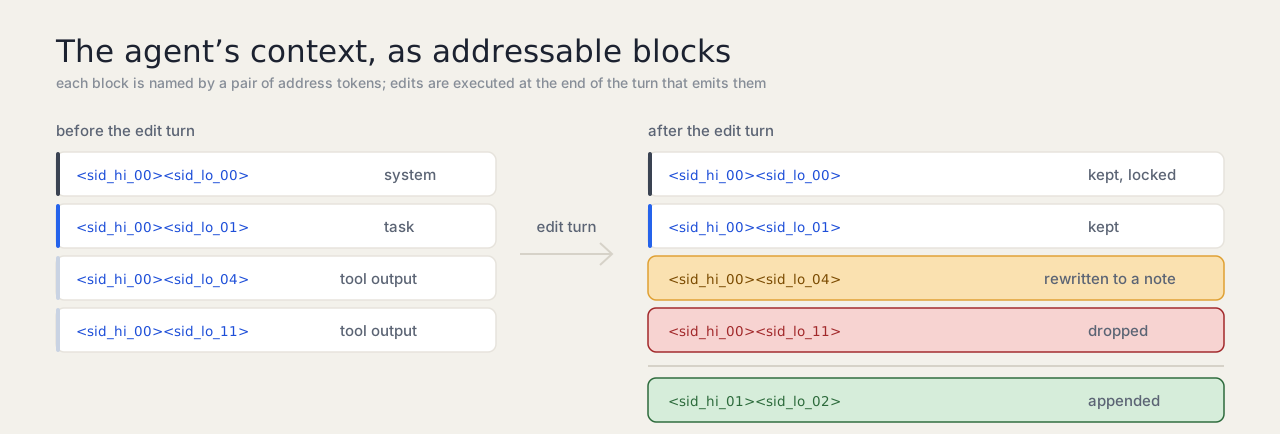
Seventy reserved tokens name the pieces of an edit. Address tokens name a block; operator tokens say what happens to it.
<sid_hi_12><sid_lo_07>
drop
rewrite
append
Editing as Language — one agent, one long task, and the edits it makes along the way: the grammar, a recorded edit turn, and the measurements behind the results.
The idea
A rule fires on size alone and cannot tell which information the task still needs. A tool call takes its meaning from a schema the harness declares in the prompt. NCE makes the edit part of the language the model already speaks, so its meaning ships with the model and holds in every harness.
Seventy reserved tokens name the pieces of an edit. Address tokens name a block; operator tokens say what happens to it.
An edit is one envelope around one operator. The rules are small enough to state in a line each, and a malformed envelope executes as a no-op.
Each well-formed edit binds to exactly one transition of the context state, executed by a task-agnostic runtime, in every harness.
Method
Recorded trajectories contain no edits. Two teachers annotate them, and training follows the context as it is edited, so each decision is supervised on the context the agent will actually face.
Long-horizon runs from Terminal-Bench and SWE-bench, with no edits of any kind.
Reads the full trajectory and assigns each block a release point: the turn after which it may be edited. A block is released only when the teacher can cite the event that ended its use.
Sees only the blocks and the release annotations available at that turn, and decides when and how to edit. The edits are therefore safe to learn and executable by an agent that cannot see ahead.
Each edit executes at the end of the turn that issues it, and every later decision is built on the resulting context, matching inference time exactly.
The model generates a turn, the runtime executes the edits it contains, and generation resumes from the edited context.
Results
Evaluated on four long-horizon agentic benchmarks at a 256K budget: Terminal-Bench 2.0, SWE-bench Verified, SWE-bench Multilingual, and SWE-bench Pro.
Success rate (%) and tokens per task (×106, 10% trimmed mean over tasks).
| Benchmark | Success (%) ↑ | Tokens (×106) ↓ | ||||
|---|---|---|---|---|---|---|
| Comp. | Tools | NCE | Comp. | Tools | NCE | |
| TB 2.0 | 32.6 | 32.6 | 38.2+5.6 | 6.62 | 6.38 | 4.60−31% |
| SWE Verified | 65.2 | 62.4 | 70.0+4.8 | 4.07 | 3.40 | 2.70−34% |
| SWE Multilingual | 56.0 | 54.3 | 62.3+6.3 | 10.83 | 10.93 | 6.12−44% |
| SWE Pro | 39.4 | 39.7 | 44.9+5.5 | 9.50 | 8.46 | 6.42−32% |
| Average | 48.3 | 47.3 | 53.9+5.6 | 7.76 | 7.29 | 4.96−36% |
The same training recipe transfers to a second base model.
| Benchmark | Success (%) ↑ | Tokens (×106) ↓ | ||
|---|---|---|---|---|
| Comp. | NCE | Comp. | NCE | |
| TB 2.0 | 38.2 | 43.8+5.6 | 2.98 | 3.04+2% |
| SWE Verified | 69.8 | 74.0+4.2 | 2.92 | 2.19−25% |
| SWE Multilingual | 58.0 | 64.3+6.3 | 5.12 | 4.13−19% |
| SWE Pro | 43.6 | 45.3+1.7 | 5.82 | 4.92−15% |
| Average | 52.4 | 56.9+4.5 | 4.21 | 3.57−15% |
Success rate (%) for LongCat as the budget shrinks. The advantage over harness compaction widens as the window tightens.
| Method | 256K | 128K | 64K | 48K |
|---|---|---|---|---|
| Harness compaction | 32.6 | 25.8 | 27.0 | 20.2 |
| Tool-call editing | 32.6 | 30.3 | 29.2 | 27.0 |
| NCE | 38.2 | 34.8 | 32.6 | 30.3 |
Interactive
Step through a real run turn by turn: the block list changes as edits execute, the token count falls, and the agent keeps working.
Citation
@misc{deng2026nce,
  title         = {Editing as Language: Teaching {LLM} Agents a Grammar for Native Context Editing},
  author        = {Yunlong Deng and Yan Li and Xing Hu and Yida Zhu and Sean Du and Weiyang Liu and Guangyi Chen},
  year          = {2026},
  eprint        = {2610.25550},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  url           = {https://github.com/dengyl20/native-context-editing}
}